Project Description
Case Studies / AI & ML
AI & ML
Effective Speech Separation System For Enhanced Podcast Delivery
Our client is a podcast production company that creates and edits engaging podcast episodes for a diverse range of topics.
Book a strategy call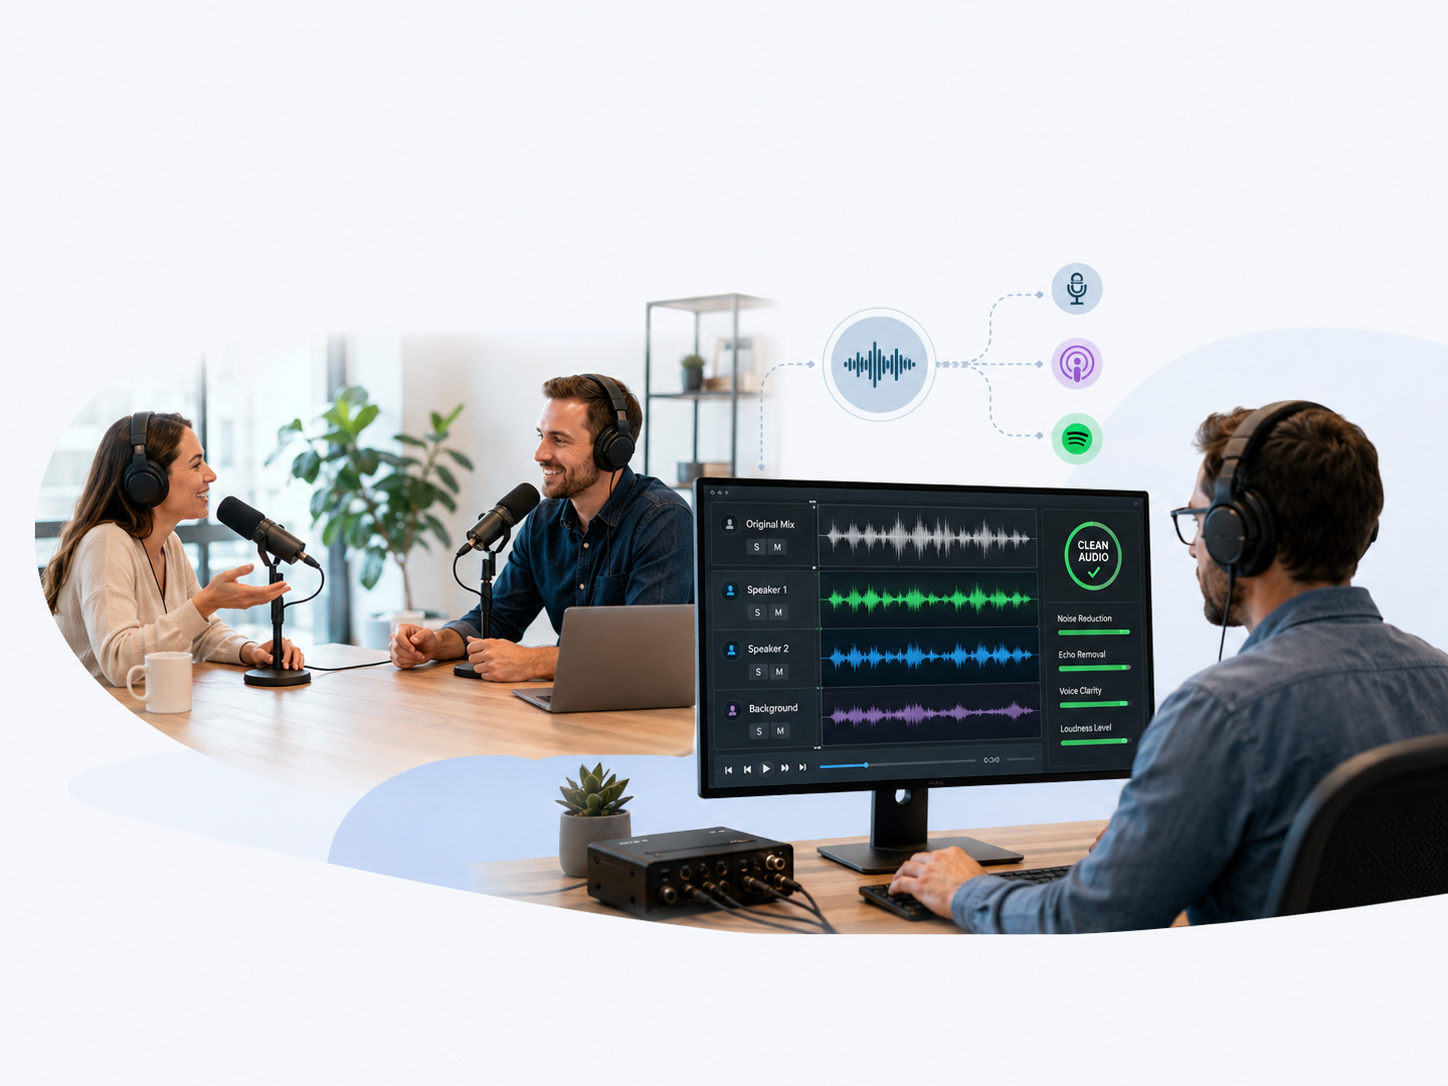
The Client
Client Overview
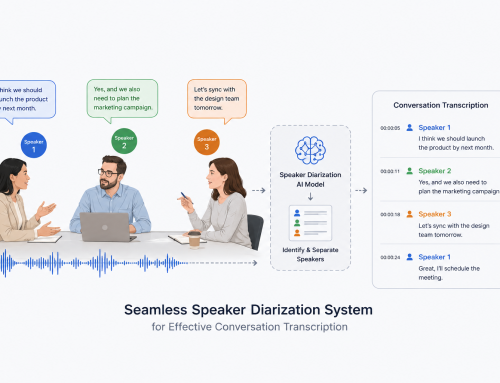
Our client is a podcast production company that creates and edits engaging podcast episodes for a diverse range of topics. They faced challenges related to overlapping speech and background noise, as multiple hosts and guests often spoke simultaneously. Additionally, environmental and ambient noises also contributed to the audio quality issues. To address this issue, the client sought a speech separation system that could optimize audio quality and enhance the clarity of the podcast episodes.
01
Challenges
Build a speech separation system for multiple speakers where speakers overlap while speaking.
The system should be able to handle simultaneous speakers with varying tones and accents.
The system should improve audio quality by accurately identifying speech occurrences and differentiating background noises.
02
Approach
Technical implementation
- SpeechBrain- an open-source speech processing toolkit is used.
- Created LibriMix dataset, by combining audios from the Librispeech dataset.
- Developed a transformer-based, deep-learning, separation model architecture.
- Trained the separation model on an NVIDIA A100 GPU instance with preprocessed audio data to predict the separated sources.
- Applied an inference script using the trained model to process the multiple-speaker audio input and generate predictions for separated sources.
- Combined the separate sources to reconstruct the individual clean audio signals using an inverse transformation.
03
Impact
17% time-saving per recording session and an 8% increase in participant engagement.
Communication-related errors decreased by 14% and reduction in repetition by 7%.
Improvement in the audio and voice quality by 12% and reduction in false positives by 5%
Want results like these from your own data?
Talk to a specialistSee how you could get similar results
Rudder Analytics builds data and AI systems that ship — and stay tied to accuracy, cost, and customer experience.